The Brief
SAP has expanded its Business Data Cloud with native Databricks lakehouse integration and an AI-native Ontology Manager. The update bridges enterprise ERP context with analytical lakehouse assets, allowing autonomous agents to query and reason across complex business entities without custom middleware.
Enterprise analytics architecture is undergoing a structural pivot towards autonomous execution. While early corporate AI efforts focused on generative dashboards and ad-hoc chat summaries, organisations are now operationalising autonomous agents capable of conducting end-to-end analytical investigations. These multi-step workflows require models to evaluate contradictory records, formulate follow-up SQL queries, and trigger workflows across multiple systems of record.
At the annual SAP TechEd conference, SAP announced major expansions to its Business AI Platform and Business Data Cloud (BDC), introducing the SAP Business Data Cloud Ontology Manager alongside native Databricks integrations. The release directly tackles the primary bottleneck hindering enterprise AI deployment: the semantic disconnect between transactional operational software and analytical data warehouses.
Unifying Business Semantics with the Lakehouse
Historically, data engineering teams had to design bespoke ingestion pipelines to replicate enterprise resource planning (ERP) schemas into separate data lakes. This brittle architecture often stripped out the contextual relationships, business rules, and entity definitions that operational applications depend upon. When autonomous agents interrogate disconnected data lakes, they frequently misinterpret custom field relationships or return hallmarked figures based on stale tables.
The new BDC Ontology Manager provides an AI-native authoring environment that constructs unified business ontologies across SAP and third-party estates. By embedding domain logic into data structures, models can comprehend how ledger entries, purchase orders, and customer records relate across operational silos. Concurrently, the incorporation of Databricks capabilities: including Lakeflow, Agent Bricks, Unity Gateway, and Lakebase: brings lakehouse scalability directly into the governed SAP context layer.
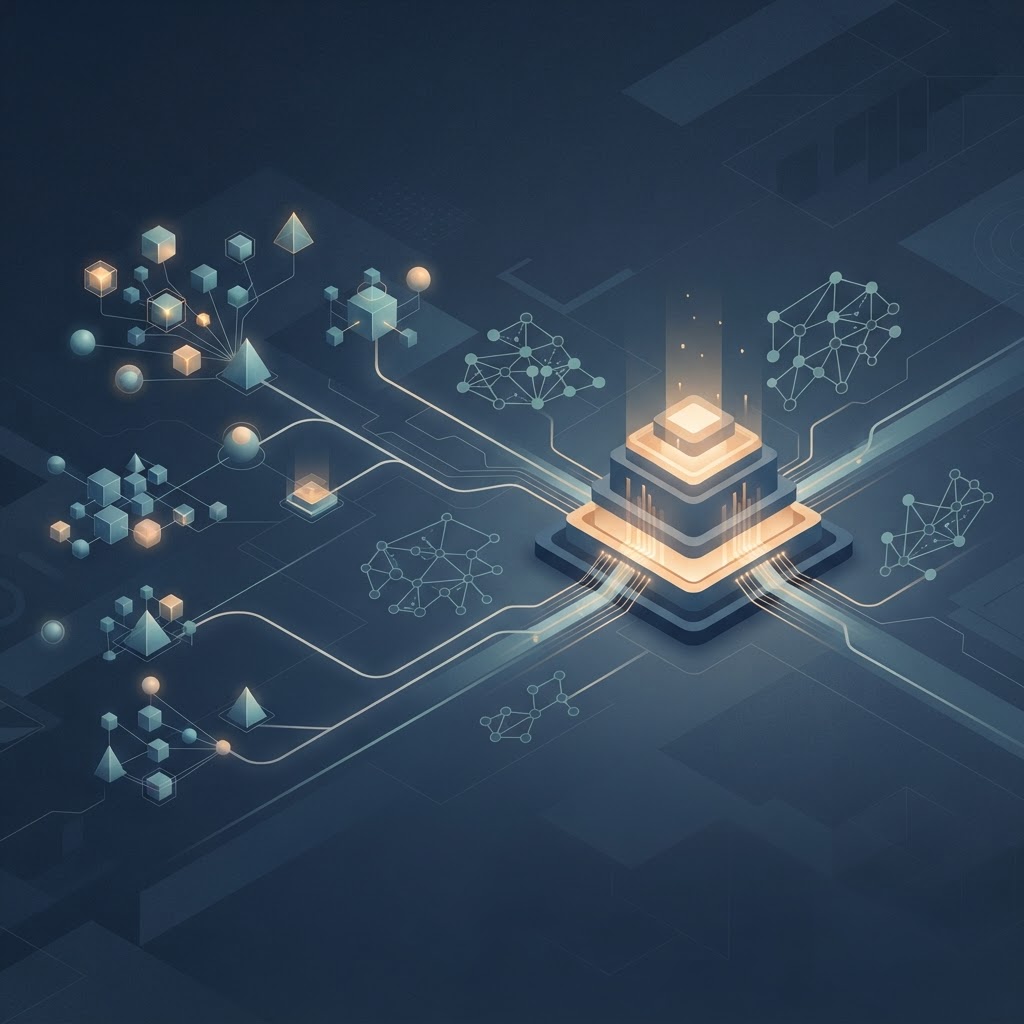
- 01Ontology ModellingTeams define cross-system business semantics and relational logic inside the AI-native authoring layer.
- 02Zero-Copy FederationDatabricks Unity Gateway connects transactional ERP data directly with analytical lakehouse assets.
- 03Agent ReasoningAutonomous agents interpret analytical questions and formulate multi-step execution plans across validated sources.
- 04Governed ExecutionJoule Studio runtimes enforce strict enterprise access controls before agents alter downstream production systems.
Illustrative design pattern, not a vendor architecture.
The Industry Shift Toward Agent-Ready Semantics
The SAP announcement reflects a wider industry pivot where data platform vendors race to standardize data models for agent consumption. As highlighted in research by Snowflake on building data foundations for agentic analytics, enterprise platforms must move away from static dashboard serving to support interactive, non-linear reasoning paths that adapt as agents uncover intermediate results. Without standardized protocols and semantics, data engineering teams face unsustainable maintenance overheads.
| Architectural Layer | Traditional Lakehouse Setup | Autonomous Agent-Ready Fabric |
|---|---|---|
| Context Definition | Disconnected semantic layers and manual dbt docs | Centralized machine-readable ontology layer |
| Query Pattern | Predictable BI dashboards and human analyst queries | Dynamic, non-linear exploratory agent queries |
| Cross-Platform Access | Fragile ETL pipelines and duplicate staging tables | Governed zero-copy federation and runtime protocols |
| Execution Boundaries | Broad role-based permissions per schema | Granular, agent-identity execution and action constraints |
Analytical leaders are increasingly recognizing that pipeline development is evolving from simple batch transformation to semantic orchestration. As documented in research by TDWI on trends reshaping data engineering, the proliferation of autonomous enterprise agents requires organizations to rethink foundational data delivery, shifting priority toward verifiable business definitions and hardened execution guardrails.
Practical Implications for Engineering and Analytics Careers
For enterprise data engineers, this shift redefines pipeline design. Instead of spending workweeks building extract-transform-load (ETL) scripts to move ERP tables into cloud warehouses, engineers must focus on ontology engineering, metadata harmonization, and semantic graph construction. Understanding how systems like Databricks Unity Catalog and enterprise ontologies expose schemas to AI models is quickly becoming an essential skillset.
For business analysts and data practitioners, the arrival of agentic analytics changes day-to-day work from manual data extraction to governance and intent design. Analysts will increasingly define the objective functions, validation thresholds, and semantic rules that guide autonomous investigations. Rather than compiling weekly reports, practitioners will monitor multi-agent runtimes to ensure agents interpret transactional datasets correctly.
Actionable Takeaway
Data and analytics teams should audit one high-friction cross-departmental reporting pipeline, such as order-to-cash or supply forecasting. Instead of building additional intermediary reporting views, map the underlying tables to a unified machine-readable ontology and test whether open query agents can accurately infer relationships without custom extraction code.